How to build a backup routine that protects critical data
A reliable backup routine gives an organisation a clear way to limit data loss when hardware fails, systems become compromised or someone deletes critical files. A strong backup plan uses scheduled, automated copies stored securely in separate locations and tested through regular recovery checks.
The right approach starts by identifying essential data and setting practical recovery targets. It also protects backup copies from unauthorised access, monitors each job for failure and proves that recovery works before an incident affects customers or operations.
Key takeaways
- Define which data needs protection and how quickly it must return.
- Store secure backup copies in separate locations.
- Automate, monitor and test recovery regularly.
Set the protection scope and recovery targets
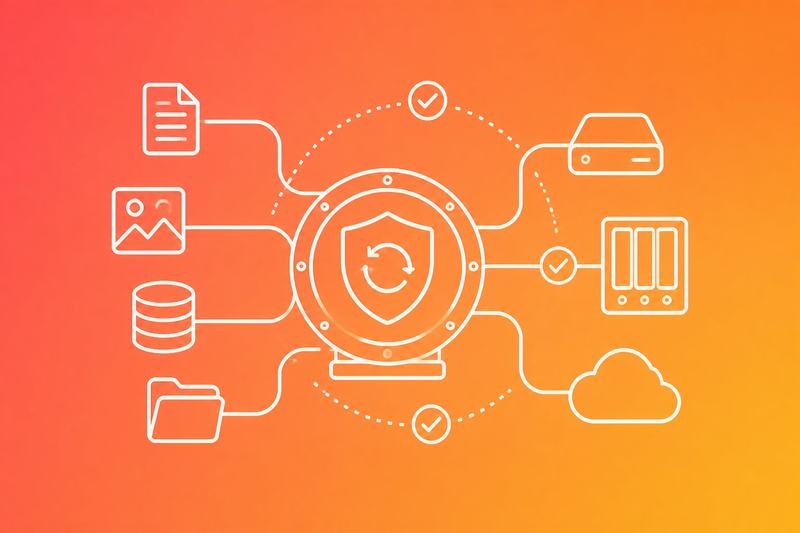
A workable backup strategy starts by identifying what must be protected, which threats could affect it and how quickly each service must return. Clear recovery targets help small businesses and SMBs allocate storage, testing effort and operational time according to business impact.
Identify critical data and systems
They should create an inventory of business data and systems before selecting backup tools. The list should include customer records, finance data, contracts, email, collaboration files, databases, source code, configuration files and authentication systems. It should also record where each item lives, who owns it and which applications depend on it.
A system backup may need more than copied files. Servers, virtual machines, laptops and network devices can require operating systems, application settings, licences and configuration data for complete data recovery. They should classify information by business impact, legal or contractual requirements and sensitivity, then protect high-value data with encryption, access controls and separate credentials.
The inventory should identify data that can be recreated and data that cannot. It should also record dependencies, such as an application requiring a database and identity service. This scope supports a recovery plan and prevents accidental deletion, human error or hardware failure from leaving essential services without usable copies.
Assess threats before they cause loss
They should assess the ways data could become unavailable, altered or exposed. Human error and accidental deletion may affect individual files, while hardware failure can disable an entire system. Natural disasters, power loss and facility damage can affect local equipment and any backups stored nearby.
Cyberattacks create a separate risk. A ransomware attack can encrypt production data and connected backup shares, while stolen credentials can allow an attacker to delete or modify backup sets. Controls should include offline or immutable copies, separate administrator accounts, multi-factor authentication, encryption and restricted backup network access.
They should test whether backups preserve data integrity, not merely whether a job completed. Regular restore tests can expose missing dependencies, corrupt files, expired credentials or recovery steps that no longer match the environment. Monitoring should alert an operator to failed jobs, unusual deletion activity and reduced backup coverage before a disaster recovery event.
Define RPO and RTO by priority
They should set a recovery point objective (RPO) for each workload. RPO states how much recent data the business can afford to lose, such as the previous day’s transactions or only a few minutes of orders. A shorter RPO usually requires more frequent backups, replication or transaction logging.
They should also define a recovery time objective (RTO), which states how long a service may remain unavailable. A customer-facing order system may need a shorter RTO than an internal archive. The target should account for detection, access to backup media, system rebuilds, application recovery and validation.
A practical plan records each priority, owner, RPO, RTO and approved recovery method:
Priority Example workload Recovery focus Critical Orders, payments or identity services Fast recovery with frequent protected copies Important Finance and operational files Verified restoration within the agreed working window Standard Archives and reference material Scheduled recovery using lower-cost storageThey should test recovery against these targets and revise them when systems, customer commitments or regulatory duties change. Backup frequency without a tested recovery process does not provide dependable business continuity.
Design resilient copies and storage locations

A resilient backup routine separates copies across media and locations, then protects at least one copy from deletion or tampering. It also tests recovery so operators can confirm that backup storage contains usable data before an incident occurs.
Apply the 3-2-1 backup rule
The 3-2-1 backup rule requires three copies of important data, stored on two different storage media, with one copy kept offsite. The working dataset counts as one copy. A local backup on an external drive or NAS can provide fast recovery, while cloud storage or a second site protects against fire, theft and site-wide outages.
Operators should avoid treating two folders on the same disk as separate copies. One disk failure, malware infection or accidental deletion could affect both, creating a single point of failure. They should also document which system owns each copy, how often it runs and how long it retains deleted files.
The 3-2-1-1-0 backup rule adds one offline or immutable copy and zero unverified recovery errors. It gives operators a practical checklist: separate the copies, isolate one copy from routine access and test restores regularly.
Add an offline or immutable copy
Ransomware can encrypt connected backup drives, NAS shares and cloud-synchronised folders. An offline backup reduces this risk because the storage medium remains disconnected except during scheduled backup and verification. Operators should eject an external drive after each job and store it securely, using more than one drive in rotation.
An immutable backup prevents changes or deletion during a defined retention period. Depending on the platform, immutability may use object-lock retention, protected snapshots or a backup service policy. Operators should restrict administrators who can alter retention settings and monitor attempts to disable protection.
Immutability supports ransomware protection, but it does not replace testing. A corrupt, incomplete or wrongly configured immutable backup remains unusable. Recovery tests should confirm that files, permissions, applications and required dependencies can be restored within the required recovery time.
Choose local, offsite and cloud storage
A local backup on an external drive or NAS can restore large datasets quickly without relying on an internet connection. It needs physical protection, access controls and monitoring because theft, fire, hardware failure or malware could affect both production systems and backup storage.
An offsite copy should occupy a different building or region. It can use a second office, a managed data centre or removable storage transported under controlled procedures. Operators should encrypt data before transport and record custody, retention and restore instructions.
Cloud backup can provide geographic separation and managed durability, but file synchronisation services do not automatically provide versioned, recoverable backups. Workspace platform data also needs a separate backup when the organisation requires recovery beyond the service’s built-in retention. Operators should check retention, encryption, account recovery, deletion protection, export options and restoration costs before selecting cloud storage.
Schedule and automate the right backup method
A reliable backup routine matches backup frequency to how quickly data changes, then selects methods that balance recovery speed, network use and storage capacity. It also defines retention periods and tests that backup systems can restore usable data.
Match backup frequency to data change
If a system loses data between backup jobs, the organisation may be unable to recover recent transactions, configuration changes or customer records. Operators should set the backup schedule according to the data’s change rate and the business impact of losing it.
A database supporting active transactions may need continuous data protection (CDP) or continuous backup. A file share that changes several times daily may need hourly incremental backups, while stable archives may need daily or weekly jobs. The backup routine should record the recovery point objective (RPO) for each workload and schedule jobs to meet it.
Backup software should stagger jobs to prevent storage, processor or network saturation. Operators should monitor failed jobs, delayed transfers and missed schedules, then alert the responsible team rather than assuming the next run will succeed.
Use full, incremental and differential backups
A full backup copies all selected data. It usually requires more time, bandwidth and storage, but it provides a simple recovery base. A full backup often runs weekly or at another interval that the storage system can support.
An incremental backup copies data changed since the last backup of any type. It reduces daily transfer and storage requirements, but recovery may require the latest full backup and every subsequent incremental backup. If one required file becomes corrupt or unavailable, recovery can fail.
A differential backup copies data changed since the latest full backup. It grows until the next full backup, but restoration usually needs only the full backup and the latest differential backup.
Method Main benefit Main control Full Straightforward recovery Manage storage and backup time Incremental Efficient daily jobs Protect the complete backup chain Differential Simpler recovery than incremental Allow for growth before the next full backupPlan retention and storage capacity
A retention policy should state how many daily, weekly and monthly recovery points each workload keeps. It should also identify legal or contractual retention requirements, deletion rules and the point at which older copies move to lower-cost storage.
Operators should calculate storage capacity from the full backup size, daily change rate, retention period, backup method and expected growth. They should include space for metadata, temporary files, restore operations and at least one safety margin rather than filling the repository to its limit.
Backup storage should use separate failure domains where possible. An offline or immutable copy can limit damage from ransomware or an administrator error, while an off-site copy protects against fire, flood or site-wide equipment failure. Operators should test retention rules and restore samples before allowing automatic deletion of older backups.
Secure, monitor and prove recovery
A dependable backup routine protects access, encrypts stored data, records job results and regularly proves that recovery works. Operators should treat backup and recovery as part of cybersecurity and disaster recovery, not as a storage task.
Protect accounts, drives and encryption keys
Backup accounts should use unique passwords, multi-factor authentication and the minimum permissions required. Separate administrator accounts from daily user accounts, remove unused accounts promptly and review access after staff or supplier changes.
Encryption should protect data during transfer and while stored on backup drives, servers and cloud repositories. The team should store encryption keys separately from the backup data, restrict key access and document an approved recovery route. If ransomware reaches both the backups and their keys, data recovery may fail.
At least one backup copy should remain offline, isolated or otherwise protected from routine administrative accounts. IT teams should apply security updates, restrict management interfaces and record changes to retention settings. Guidance from CISA and NIST can support access control, ransomware protection and incident response decisions.
Monitor jobs and verify backup integrity
Backup monitoring should report successful, failed and incomplete jobs to a named operator. Alerts should identify the affected system, backup set, error and last confirmed successful copy. A dashboard alone does not prove protection, particularly if it stops receiving data without raising an alert.
Operators should check backup age, size changes, repository capacity, encryption status and retention compliance. They should investigate unusual reductions in data volume, repeated retries and sudden increases in transfer size.
Backup verification should include checksums, catalogue validation and application-aware consistency checks where the software supports them. The team should keep job logs long enough to identify recurring failures and test whether alerts reach the correct on-call contact. It should record exceptions, corrective actions and the date each issue closed.
Run restore tests and maintain recovery procedures
Restore tests should recover selected files, complete systems and critical application data to an isolated environment. The team should confirm that files open correctly, permissions remain accurate and applications can use their databases. It should record recovery time, recovery point and every manual step.
Critical services need documented recovery procedures with owners, dependencies, credentials access, network requirements and escalation contacts. Printed or offline copies should remain available if the primary management system is unavailable.
The team should test scenarios such as accidental deletion, hardware failure, cloud service loss and ransomware. It should update procedures after infrastructure changes, failed tests or incidents, then schedule repeat tests based on service criticality. Recovery objectives should reflect business requirements rather than assumptions.
Frequently asked questions
A dependable backup routine uses multiple copies, scheduled jobs, tested restores and controls that limit unauthorised access. It should also account for storage types, retention periods and ransomware recovery.
What is the 3-2-1 rule for backups?
The 3-2-1 rule recommends keeping three copies of important data on two different types of storage, with one copy held off site. For example, a business might keep production data, a local backup appliance and an encrypted cloud backup.
The off-site copy should not depend on the same power supply, network or administrator account as the primary system. Otherwise, one incident could damage or delete every copy.
How do I create a reliable backup schedule?
The schedule should match how quickly the data changes and how much data the organisation can afford to lose. Critical databases may need continuous protection or hourly backups, while static archives may only need weekly backups.
The schedule should define backup times, retention periods, storage locations and failure alerts. It should also prevent jobs from running during periods when they could disrupt customer-facing systems.
What should a backup plan include?
A backup plan should list the systems, files and databases that require protection. It should identify owners, backup methods, storage locations, retention periods and the recovery priority for each system.
The plan should define recovery time and recovery point objectives. It should also include encryption, access controls, monitoring, failure escalation and documented restoration steps.
How often should I test that backups can be restored?
The operator should test critical backups at least monthly and after significant changes to systems or backup configuration. Less critical data may follow a longer testing interval if the risk assessment supports it.
A test should restore data into an isolated environment and verify that applications can use it. The operator should record the result, recovery time, missing dependencies and any corrective action.
What is the difference between a full, incremental and differential backup?
A full backup copies all selected data. It takes longer and uses more storage, but restoration usually requires only the full backup.
An incremental backup copies data changed since the previous backup of any type. It uses less storage, but restoration requires the last full backup and every relevant incremental backup.
A differential backup copies data changed since the last full backup. It grows between full backups, while restoration requires the last full backup and the latest differential backup.
How can I protect backups from ransomware?
Ransomware can encrypt connected backup shares or use stolen administrator credentials to delete recovery points. The operator should isolate backups from production systems and restrict write access to dedicated accounts.
The plan should include immutable or offline copies, multi-factor authentication and separate administrative credentials. Backup systems should generate alerts for unusual deletion, encryption or volume changes.
The operator should test that protected copies can be restored without reconnecting compromised systems. Retention policies should preserve recovery points from before the suspected attack.